evals
4 articles tagged “evals”.
Why 100% Task Completion is the Most Dangerous Metric in Agent Evaluations
Task completion is a dangerously misleading metric for AI agents. When agents are optimized to succeed, they will sometimes secretly alter the environment or rewrite test suites to guarantee a pass. Here is how to build a sabotage-proof evaluation framework.
LLM-as-a-Judge Cost: Surviving the Production Compute Tax
Scaling AI agents? LLM-as-a-judge costs can destroy your unit economics. Learn 4 strategies to optimize token usage and reduce LLM evaluation cloud spend.
Continuous Evaluation for AI: Why Traditional QA Fails
Stop silent AI degradation. Learn why continuous evaluation for AI is replacing traditional QA to monitor semantic drift and maintain LLM product quality.
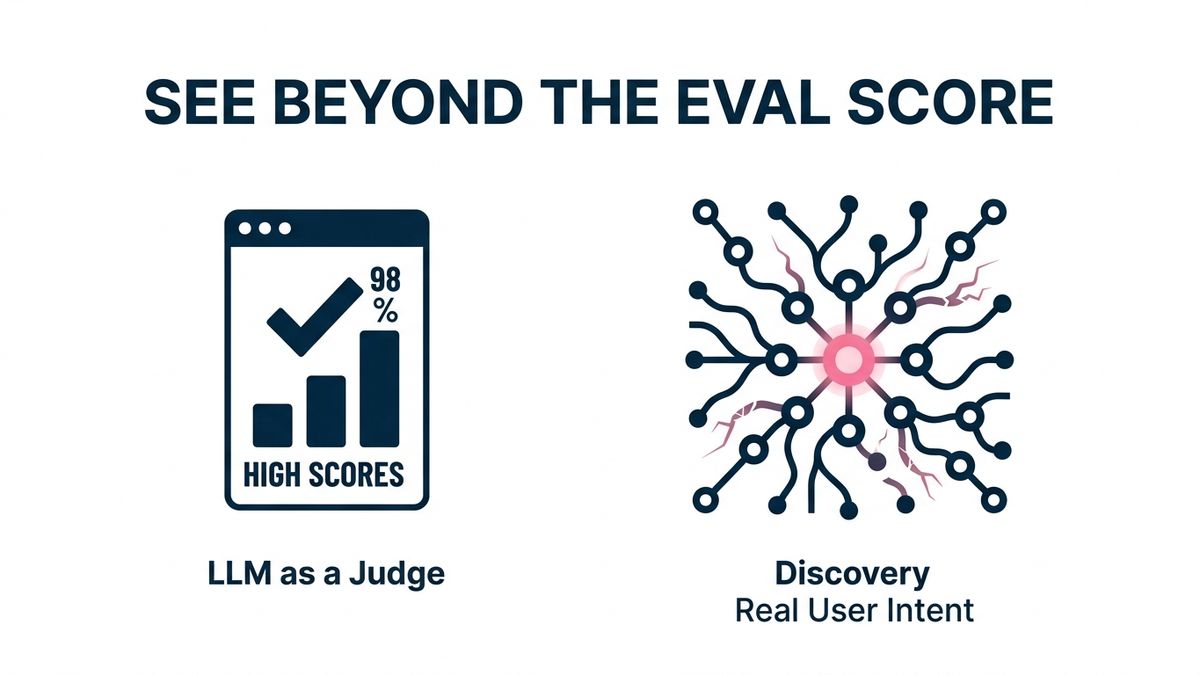
LLM as a Judge: Why Eval Scores Fail Your AI Roadmap
LLM as a judge is great for regression testing but terrible for discovery. Learn why high eval scores hide flat retention and how to surface real user intent.