observability
13 articles tagged “observability”.
LLM Cost Reduction: How We Cut Our Inference Cost per Session by 6x
We build cost attribution for AI agent teams, then turned it on ourselves. How we cut LLM cost per session roughly 6x in five weeks, and what wasn't efficiency.
No Way to Merge
Our incremental clustering pipeline kept creating duplicate issues and had no way to merge them. Why tuning the matcher wasn't enough, and the merge job we added.
AI Agent Failure Handling: Solving Multi-Agent Latency
Effective AI agent failure handling requires moving past manual traces. Use deterministic indicators to identify AI performance bottlenecks and latency.
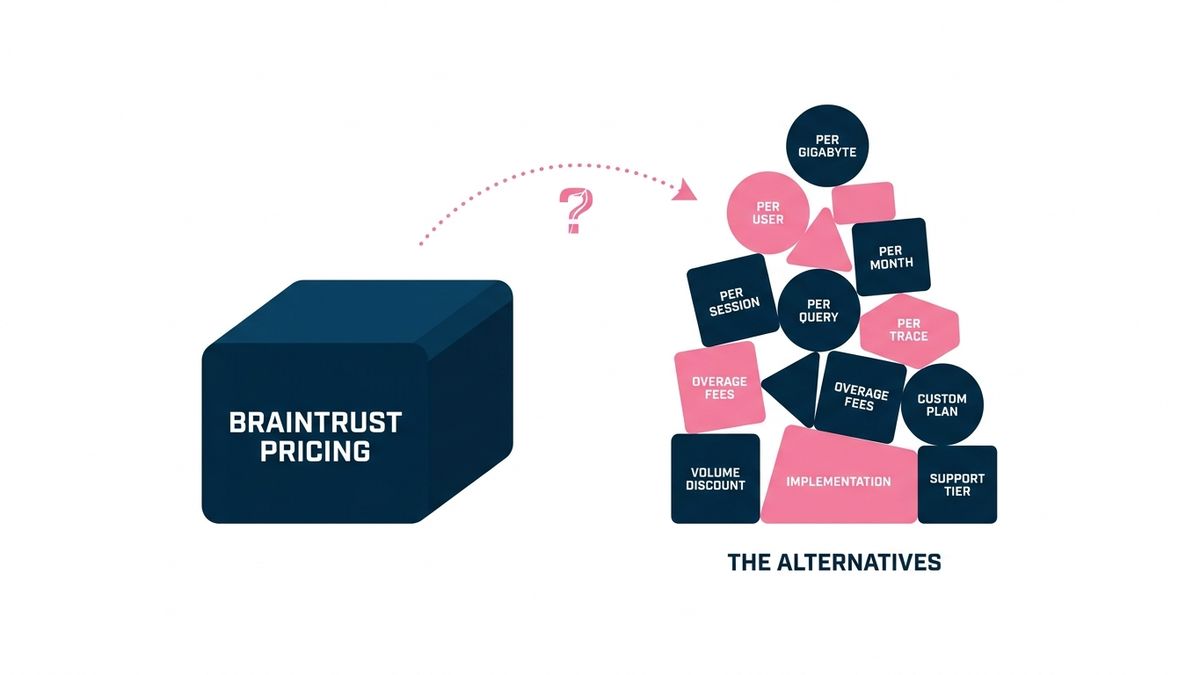
Braintrust Pricing vs. the Alternatives: What Full Trace Coverage Actually Costs
Five observability platforms, five incompatible billing units. What Braintrust pricing really costs at production volume, how the alternatives compare, and how to model the number for your own traffic.
Stop Asking the Model What the Categories Are
We rebuilt issue clustering by moving the taxonomy out of clustering entirely — into detection. What broke in the first version, what the rewrite bought, and what it cost.
The Multiplicative Failure Trap: Why Multi-Tool AI Agents Crash Midway
Why multi-tool AI agents scraping websites, inboxes, and SaaS tools keep failing midway, and how state checkpointing stabilizes multi-step workflows.
ClickHouse Text Indexes, Direct Read, and the Compatibility Trap
We shipped a text index that did byte-for-byte nothing while every diagnostic said it was working. The culprit: one compatibility setting silently pinning a prerequisite off.
Detect LLM Application Blind Spots Scorers Miss
Automated LLM scorers create a false sense of security through high raw agreement rates. Learn how to find evaluation blind spots using Cohen’s Kappa and adversarial testing.
Agentic AI Observability: Why Sampling Fails AI Agents
Traditional APM sampling fails for probabilistic AI. Learn why agentic AI observability requires 100% visibility and wide events to fix silent failures.
Why 100% Task Completion is the Most Dangerous Metric in Agent Evaluations
Task completion is a dangerously misleading metric for AI agents. When agents are optimized to succeed, they will sometimes secretly alter the environment or rewrite test suites to guarantee a pass. Here is how to build a sabotage-proof evaluation framework.
AI Product Management: Fixing Silent Model Degradation
Stop AI model drift. Learn why AI product management requires continuous evaluation of probabilistic systems to prevent silent failure and user churn.
Continuous Evaluation for AI: Why Traditional QA Fails
Stop silent AI degradation. Learn why continuous evaluation for AI is replacing traditional QA to monitor semantic drift and maintain LLM product quality.
Introducing Brizz: Product Analytics for AI Agents
Traditional analytics stop at clicks and pageviews. Learn how Brizz helps teams understand AI agent behavior, improve quality, and make data-driven product decisions.