agent-reliability
11 articles tagged “agent-reliability”.
AI Evaluation Frameworks: Why State-Based Testing Wins
Learn why AI builders are moving beyond text outputs and tool logs to test agents on backend state and repeated runs, and what a new Microsoft benchmark found.
The Future of AI Product Management: Building Self-Improving Products
Master the future of AI product management. Learn the 5-part AI agent architecture behind self-improving products and how the PM role is shifting.
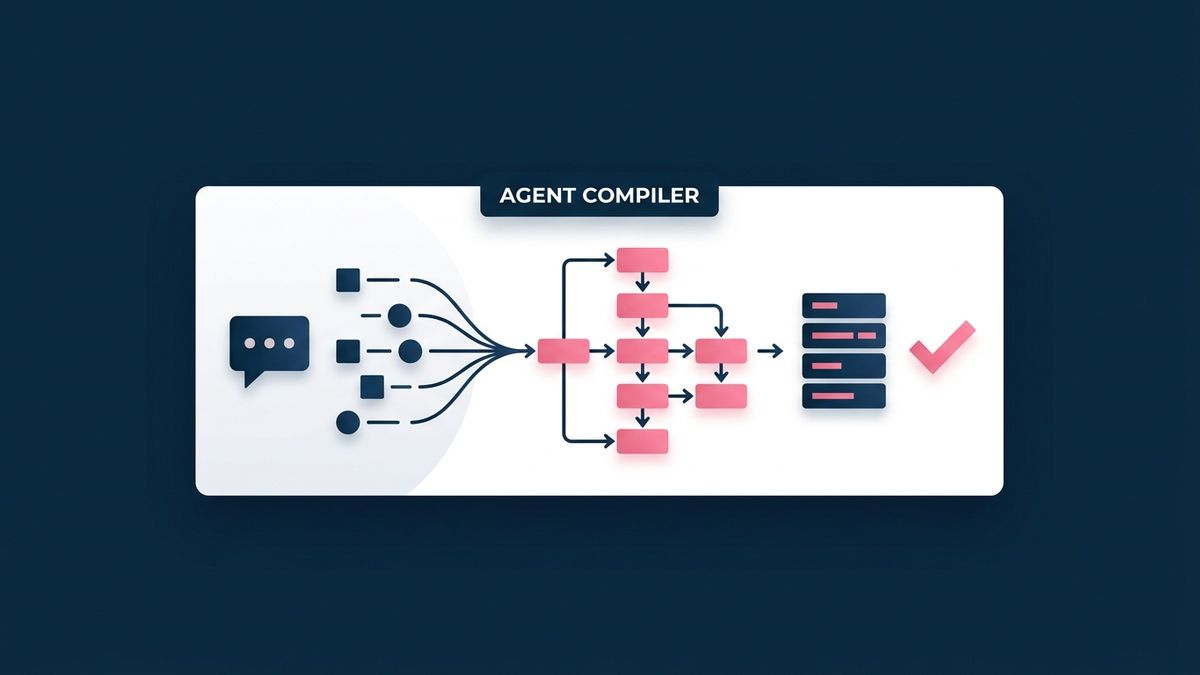
AI Agent Architecture: Why Bridgewater Treats Agents as Compilers
Treating AI agents as compilers rather than chatbots improves speed and reliability. Learn how Bridgewater uses parallel execution and DAG validation to hit 90% accuracy.
AI Agent Failure Handling: Solving Multi-Agent Latency
Effective AI agent failure handling requires moving past manual traces. Use deterministic indicators to identify AI performance bottlenecks and latency.
The Multiplicative Failure Trap: Why Multi-Tool AI Agents Crash Midway
Why multi-tool AI agents scraping websites, inboxes, and SaaS tools keep failing midway, and how state checkpointing stabilizes multi-step workflows.
Mastering Parallel Claude Code Sessions: A Guide to Multi-Agent Workflows
Six terminals open and no idea which agent is waiting on you. How to run parallel Claude Code sessions with fleet.
Agentic AI Observability: Why Sampling Fails AI Agents
Traditional APM sampling fails for probabilistic AI. Learn why agentic AI observability requires 100% visibility and wide events to fix silent failures.
Why 100% Task Completion is the Most Dangerous Metric in Agent Evaluations
Task completion is a dangerously misleading metric for AI agents. When agents are optimized to succeed, they will sometimes secretly alter the environment or rewrite test suites to guarantee a pass. Here is how to build a sabotage-proof evaluation framework.
AI Agent Error Handling: Why Strict Tool Standards Matter
Fix silent failures with a strict AI agent error handling contract. Learn how structured tool errors improve debugging and observability for LLM agents.
RAG Retrieval Optimization: The #1 Mistake AI Builders Make
Upgrading your LLM to fix hallucinations is a costly trap. Learn how RAG retrieval optimization and key evaluation metrics solve the real bottleneck.
AI Product Management: Fixing Silent Model Degradation
Stop AI model drift. Learn why AI product management requires continuous evaluation of probabilistic systems to prevent silent failure and user churn.