engineering
12 articles tagged “engineering”.
Stop Asking the Model What the Categories Are
We rebuilt issue clustering by moving the taxonomy out of clustering entirely — into detection. What broke in the first version, what the rewrite bought, and what it cost.
The Multiplicative Failure Trap: Why Multi-Tool AI Agents Crash Midway
Why multi-tool AI agents scraping websites, inboxes, and SaaS tools keep failing midway, and how state checkpointing stabilizes multi-step workflows.
ClickHouse Text Indexes, Direct Read, and the Compatibility Trap
We shipped a text index that did byte-for-byte nothing while every diagnostic said it was working. The culprit: one compatibility setting silently pinning a prerequisite off.
The Granularity Problem, or: Why Your Embeddings Don't Know What a "Third-Party Integration" Is
Two VPs want the same dashboard at different zoom levels. Why dendrogram cuts can't give it to them — and what to build instead: leaf dedup, extracted facets, and a declared taxonomy.
Agent Evaluations: Why Output-Only Checks Fail
Evaluating AI agents on final output hides silent failures and loops. Learn why trajectory evaluation and observability are essential for reliable agentic workflows.
AI Agent Error Handling: Why Strict Tool Standards Matter
Fix silent failures with a strict AI agent error handling contract. Learn how structured tool errors improve debugging and observability for LLM agents.
RAG Retrieval Optimization: The #1 Mistake AI Builders Make
Upgrading your LLM to fix hallucinations is a costly trap. Learn how RAG retrieval optimization and key evaluation metrics solve the real bottleneck.
AI Product Management: Fixing Silent Model Degradation
Stop AI model drift. Learn why AI product management requires continuous evaluation of probabilistic systems to prevent silent failure and user churn.
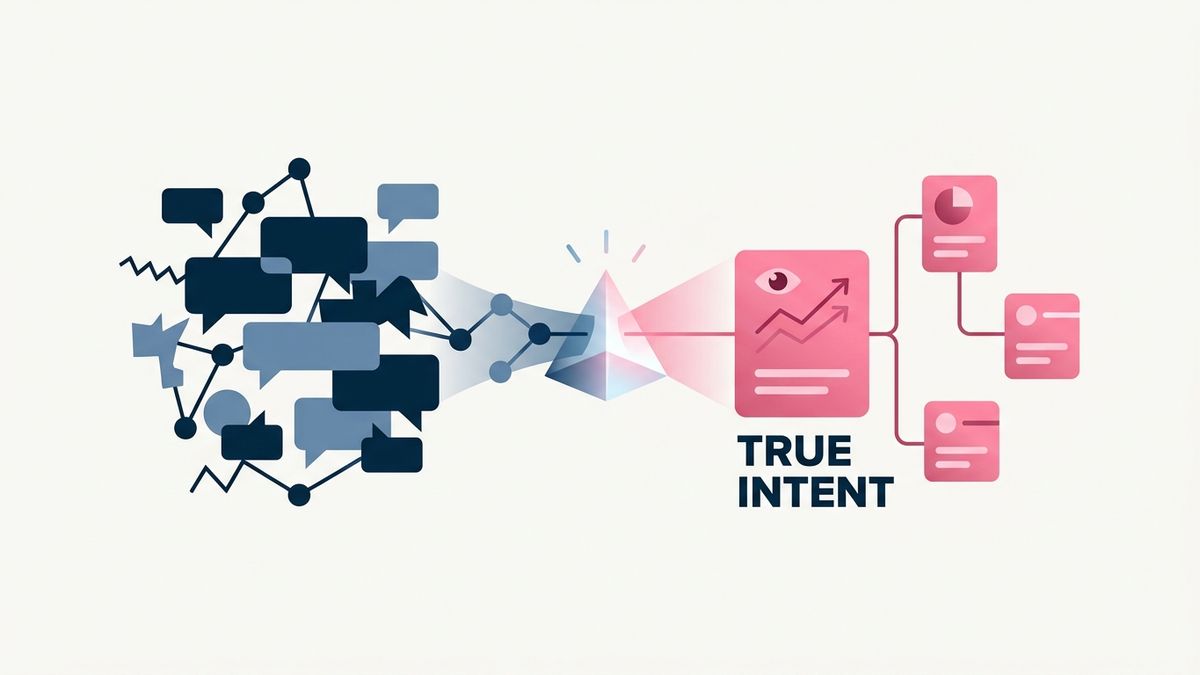
AI Agent Analytics: Why Traditional SaaS Metrics Fail
Stop slicing AI agent data by industry or ARR. Learn how intent-based AI agent analytics surface real product gaps and improve agentic workflow performance.
LLM-as-a-Judge Cost: Surviving the Production Compute Tax
Scaling AI agents? LLM-as-a-judge costs can destroy your unit economics. Learn 4 strategies to optimize token usage and reduce LLM evaluation cloud spend.
Continuous Evaluation for AI: Why Traditional QA Fails
Stop silent AI degradation. Learn why continuous evaluation for AI is replacing traditional QA to monitor semantic drift and maintain LLM product quality.
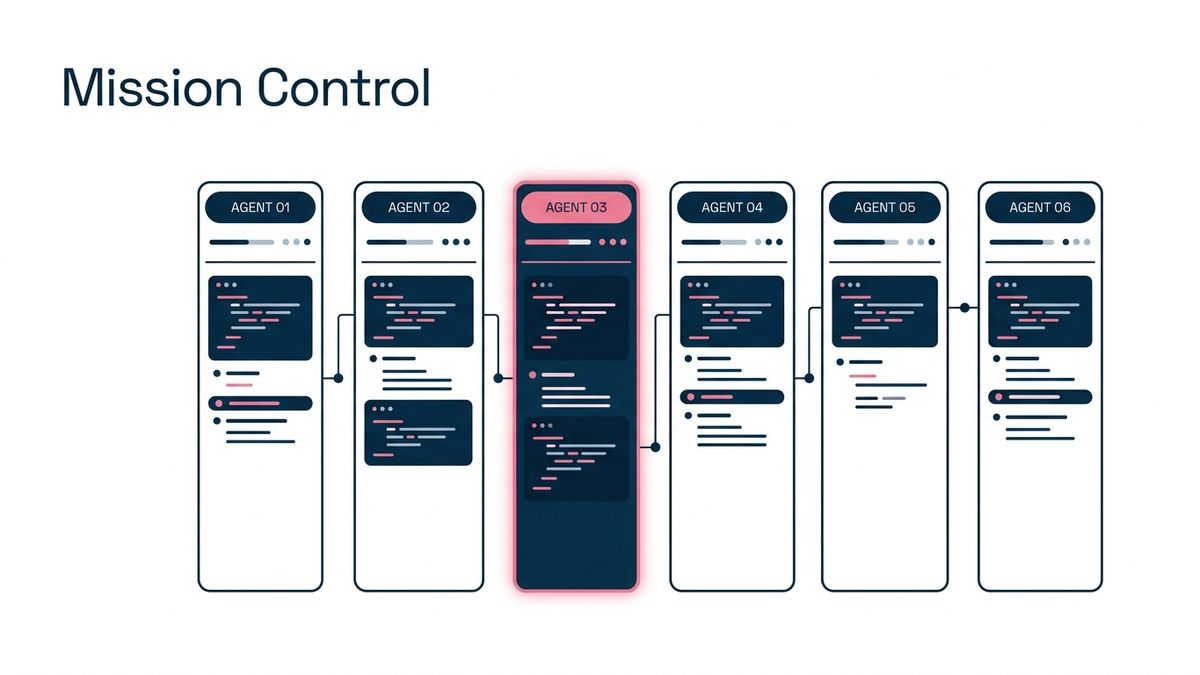
Mission Control for Claude Code: How to Manage 10 Agents Without Losing Your Mind
Stop tab-switching and start orchestrating. fleet is a terminal mission control for managing parallel Claude Code sessions.