ai-product-management
13 articles tagged “ai-product-management”.
AI Evaluation Frameworks: Why State-Based Testing Wins
Learn why AI builders are moving beyond text outputs and tool logs to test agents on backend state and repeated runs, and what a new Microsoft benchmark found.
The Future of AI Product Management: Building Self-Improving Products
Master the future of AI product management. Learn the 5-part AI agent architecture behind self-improving products and how the PM role is shifting.
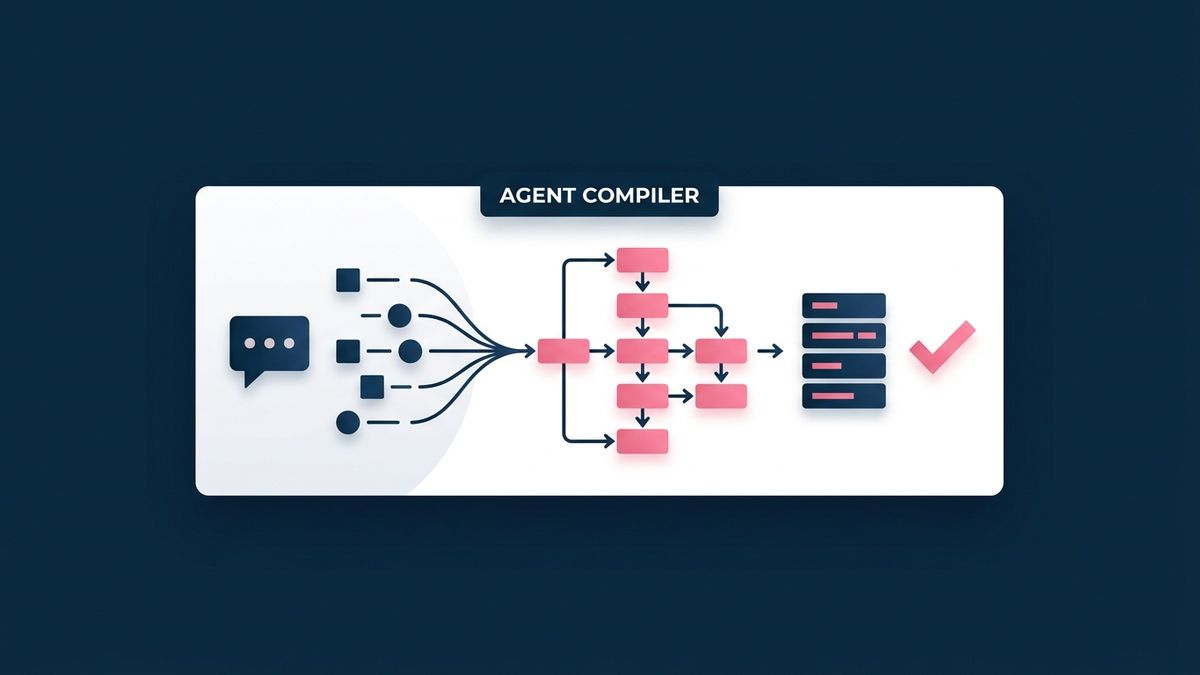
AI Agent Architecture: Why Bridgewater Treats Agents as Compilers
Treating AI agents as compilers rather than chatbots improves speed and reliability. Learn how Bridgewater uses parallel execution and DAG validation to hit 90% accuracy.
AI Agent Failure Handling: Solving Multi-Agent Latency
Effective AI agent failure handling requires moving past manual traces. Use deterministic indicators to identify AI performance bottlenecks and latency.
Claude Code Analytics: Why Anthropic Underreports AI Impact
Anthropic's new Claude Code analytics dashboard uses conservative attribution to protect developer trust. By excluding code rewritten by more than 20% and limiting matching to a strict 21-day window, they show how high-fidelity telemetry beats vanity metrics.
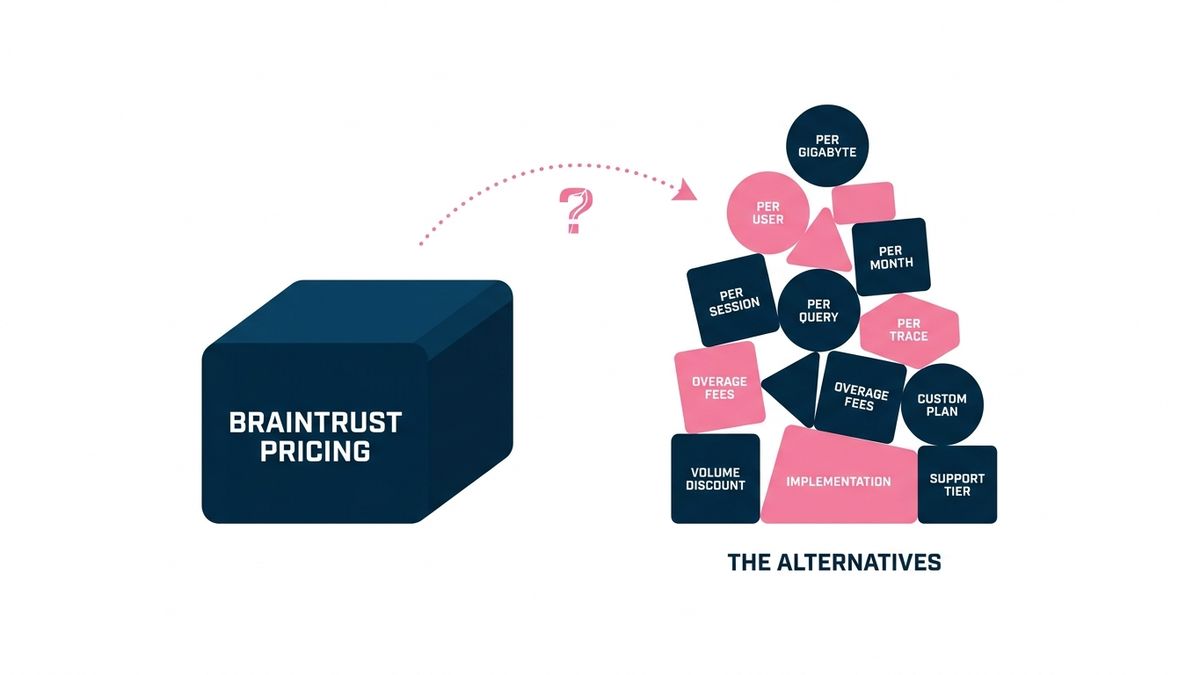
Braintrust Pricing vs. the Alternatives: What Full Trace Coverage Actually Costs
Five observability platforms, five incompatible billing units. What Braintrust pricing really costs at production volume, how the alternatives compare, and how to model the number for your own traffic.
The Granularity Problem, or: Why Your Embeddings Don't Know What a "Third-Party Integration" Is
Two VPs want the same dashboard at different zoom levels. Why dendrogram cuts can't give it to them — and what to build instead: leaf dedup, extracted facets, and a declared taxonomy.
Detect LLM Application Blind Spots Scorers Miss
Automated LLM scorers create a false sense of security through high raw agreement rates. Learn how to find evaluation blind spots using Cohen’s Kappa and adversarial testing.
Agentic AI Observability: Why Sampling Fails AI Agents
Traditional APM sampling fails for probabilistic AI. Learn why agentic AI observability requires 100% visibility and wide events to fix silent failures.
Conversational AI vs Search Bar: Building the Future of Retail
Amazon is replacing search bars with conversational AI. Learn what this format shift means for AI builders and how to measure conversational agent success.
AI Product Management: Fixing Silent Model Degradation
Stop AI model drift. Learn why AI product management requires continuous evaluation of probabilistic systems to prevent silent failure and user churn.
AI Agent Analytics: Why Traditional SaaS Metrics Fail
Stop slicing AI agent data by industry or ARR. Learn how intent-based AI agent analytics surface real product gaps and improve agentic workflow performance.
LLM as a Judge: Why Eval Scores Fail Your AI Roadmap
LLM as a judge is great for regression testing but terrible for discovery. Learn why high eval scores hide flat retention and how to surface real user intent.